๐Ÿ”ญ DRAG TO ROTATE • TAP PLANETS TO SCAN
[01] โ˜€๏ธ ABOUT CORE
[02] ๐Ÿช WORK EXPERIENCE
[03] ๐ŸŒ‹ FLAGSHIP ENGINE
[04] ๐ŸŒ FEATURED PROJECTS
[05] โ„๏ธ TECH ARSENAL
[06] โšก CERTS & GOALS
โ˜€๏ธ SECTOR 01 // ABOUT CORE & SUMMARY
Sumeet Khatri

Sumeet Khatri

Software / AI Engineer (New Grad-2026)

Strong C++ systems skills, Python backend experience, and hands-on ML infrastructure expertise. Built high-performance storage engines, low-latency inference systems, and scalable ML training workflows.

โ˜… 3-Star Coder (CodeChef) โšก 1400+ Rating (CodeForces)
๐Ÿช SECTOR 02 // WORK EXPERIENCE

Software Engineering Intern

STW Services LLP  ยท  On-site  ยท  Pune
Current Feb 2026 โ€“ Present
Internship
  • Diagnosed a data-consistency bug in a production marketplace where seller inventory updates weren't propagating to the buyer facing availability data, letting orders exceed real stock; traced the gap through the data flow and designed a synchronization fix that eliminated a class of order fulfillment failures.
  • Rebuilt a monolithic admin data view into a grouped, drill down interface to reduce rendering load and clicks to insight on high volume records.
  • Built automated reporting pipelines against a live database, fixing query filter and timezone-alignment bugs that were silently producing empty or incorrect output. Learned to verify actual data shape rather than trust it ran without errors.
DataverseJavaScriptREST APIsweb-scale databasesdata pipelinescloud platformNode.jsDatabasecompilers

Machine Learning Engineer

Owl AI (Overload Ware Labs AI)  ยท  Remote  ยท  Pune
Sep 2025 โ€“ Oct 2025
Internship
  • Optimized GPU memory footprint from ~12GB to ~3GB by fine-tuning LLaMA-3.2 3B using QLoRA on 172K reasoning samples; achieved training loss of ~0.48 after 60 epochs.
  • Integrated LoRA adapters into Q/K/V/O projection and MLP blocks, training only low-rank matrices instead of the full 3B parameters; enabled parameter-efficient chain-of-thought fine-tuning on a single GPU.
PythonPyTorchQLoRALLaMATransformersFine-Tuning
๐ŸŒ‹ SECTOR 03 // FLAGSHIP ENGINE [VULCAN]

NanoMind | Zero-Dependency C++17 LLM Inference Engine

Nov 2025 โ€“ Aug 2026  ยท  C++17, AVX2/SIMD, OpenMP, FastAPI
37.7 tok/s 2.47ร— TTFT speedup LRU KV cache <5% TPS variance 100+ MAU
  • Built a zero-dependency C++17 LLM inference engine (NanoMind) from scratch, achieving 37.7 tok/s, 2.47ร— TTFT speedup via LRU KV cache and <5% TPS variance under 1-32 concurrent users. Deployed on HuggingFace Spaces with 100+ MAU.
  • Optimized with AVX2/SIMD and OpenMP Parallelized attention heads and matmul rows, reducing latency by 60% vs. naive implementation. Pre-allocated global buffers eliminated per-request heap allocations.
  • Designed a FastAPI backend with SSE streaming, engine pooling (N=3), and latency tracking (P50/P95/P99), enabling real-time token generation for chat applications.
  • Trained a 152M-parameter GPT-2 model on 294M tokens using mixed-precision FP16 and gradient accumulation on 2x Kaggle T4 GPUs.
C++17PythonAVX2/SIMDOpenMPFastAPIDockerTransformer ArchitectureLLM Inference OptimizationAntiGravity
๐ŸŒ SECTOR 04 // FEATURED PROJECTS & SYSTEMS

CollabDocs | Real-Time Collaborative Editor

Mar 2026 โ€“ May 2026
541 ops/sec p95 1.22ms latency 140+ MAU

Built a real-time collaborative editor with a custom Operational Transformation (OT) engine in C++17, verified zero divergence across 500 randomized concurrent-edit trials. Designed high-performance WebSocket server using Boost.Asio with strand-serialized write queues and op broadcast batching.

C++17Boost.AsioWebSocketsOperational TransformationMultithreadingCMakeDockerAntiGravity

LogAI Engine | High-Throughput Telemetry Classifier

6,300+ logs/sec 99.69% coverage p50 0.019ms

Built a 3-tier log classifier (Regex โ†’ BERT/ONNX โ†’ Mistral-7B) processing 2M logs at 6,300+ logs/sec. Applied LRU cache on LLM dispatch path resolving 4,528 of 6,117 LLM-routed logs without live API calls. Diagnosed and fixed CPU starvation under batch load.

PythonBERTONNXMistral-7BRegexGradioConcurrency

KVInfer โ€“ GPT-2 Inference Engine

Nov 2025 โ€“ Mar 2026
18.7 tok/s TTFT 847ms 14 concurrent sessions

Engineered a C++ GPT-2 inference engine with SIMD and parallelism. Architected a multi-engine process pool with KV-cache and LRU eviction, sustaining 14 concurrent sessions within 8GB/16GB RAM.

C++SIMDFastAPIDockerLLM Inference

C++ Inference Engine for 50M GPT Model

Nov 2025 โ€“ Feb 2026
28.12 tok/s 35.57ms/token 61% latency reduction

CPU-optimized C++ inference engine for a 51M-parameter GPT model, achieving 28.12 tokens/sec on an Intel i3-12th Gen CPU. Reduced per-token latency 91.87ms โ†’ 35.57ms by eliminating heap allocations and parallelizing with OpenMP & AVX2/FMA kernels.

C++PythonFastAPIOpenMPAVX2/SIMD
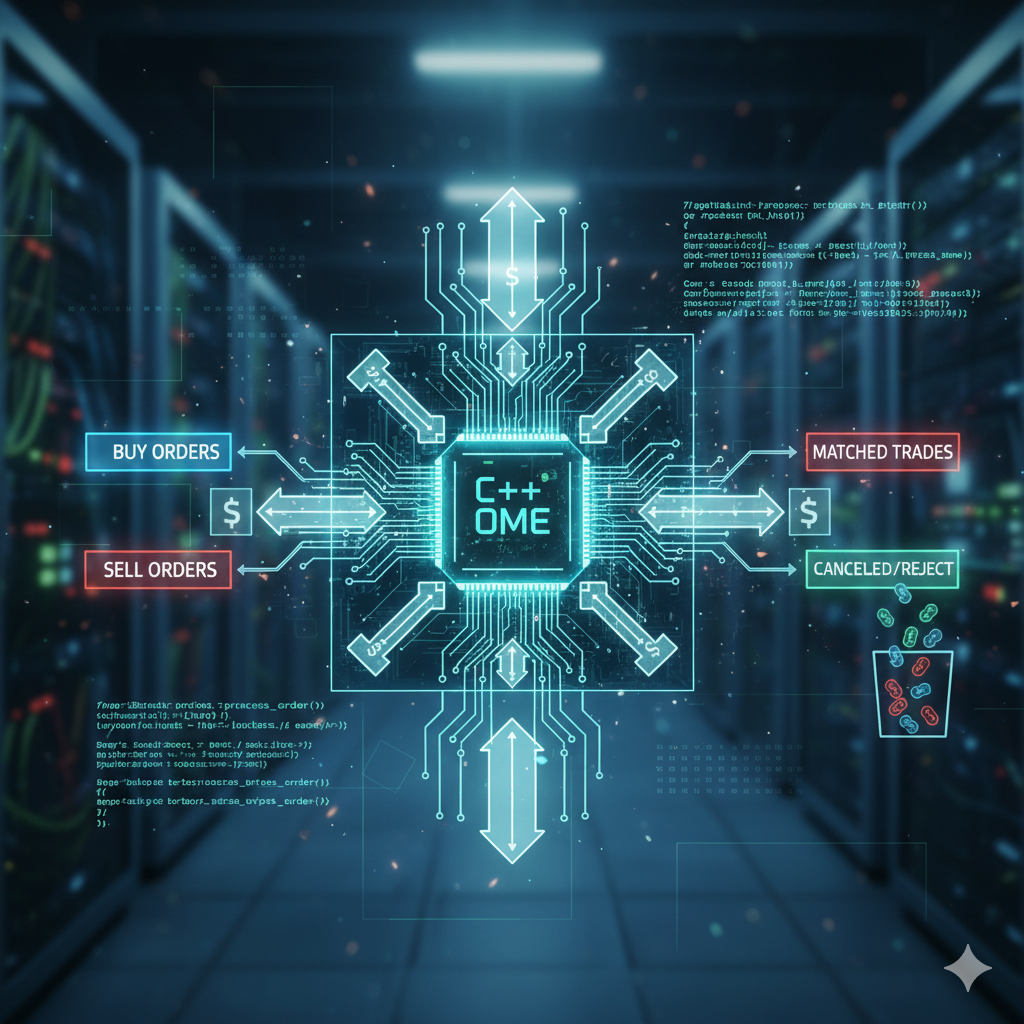
C++ Order Matching

C++ High-Performance Order Matching Engine

Aug 2025 โ€“ Jan 2026
53K+ orders/sec20K orders in 375ms

Engineered a robust Order Matching Engine in C++20 using std::map for strict price-time priority and std::unordered_map for O(1) lookups. Validated with a comprehensive GoogleTest framework.

C++20STLMultithreadingGoogle Test
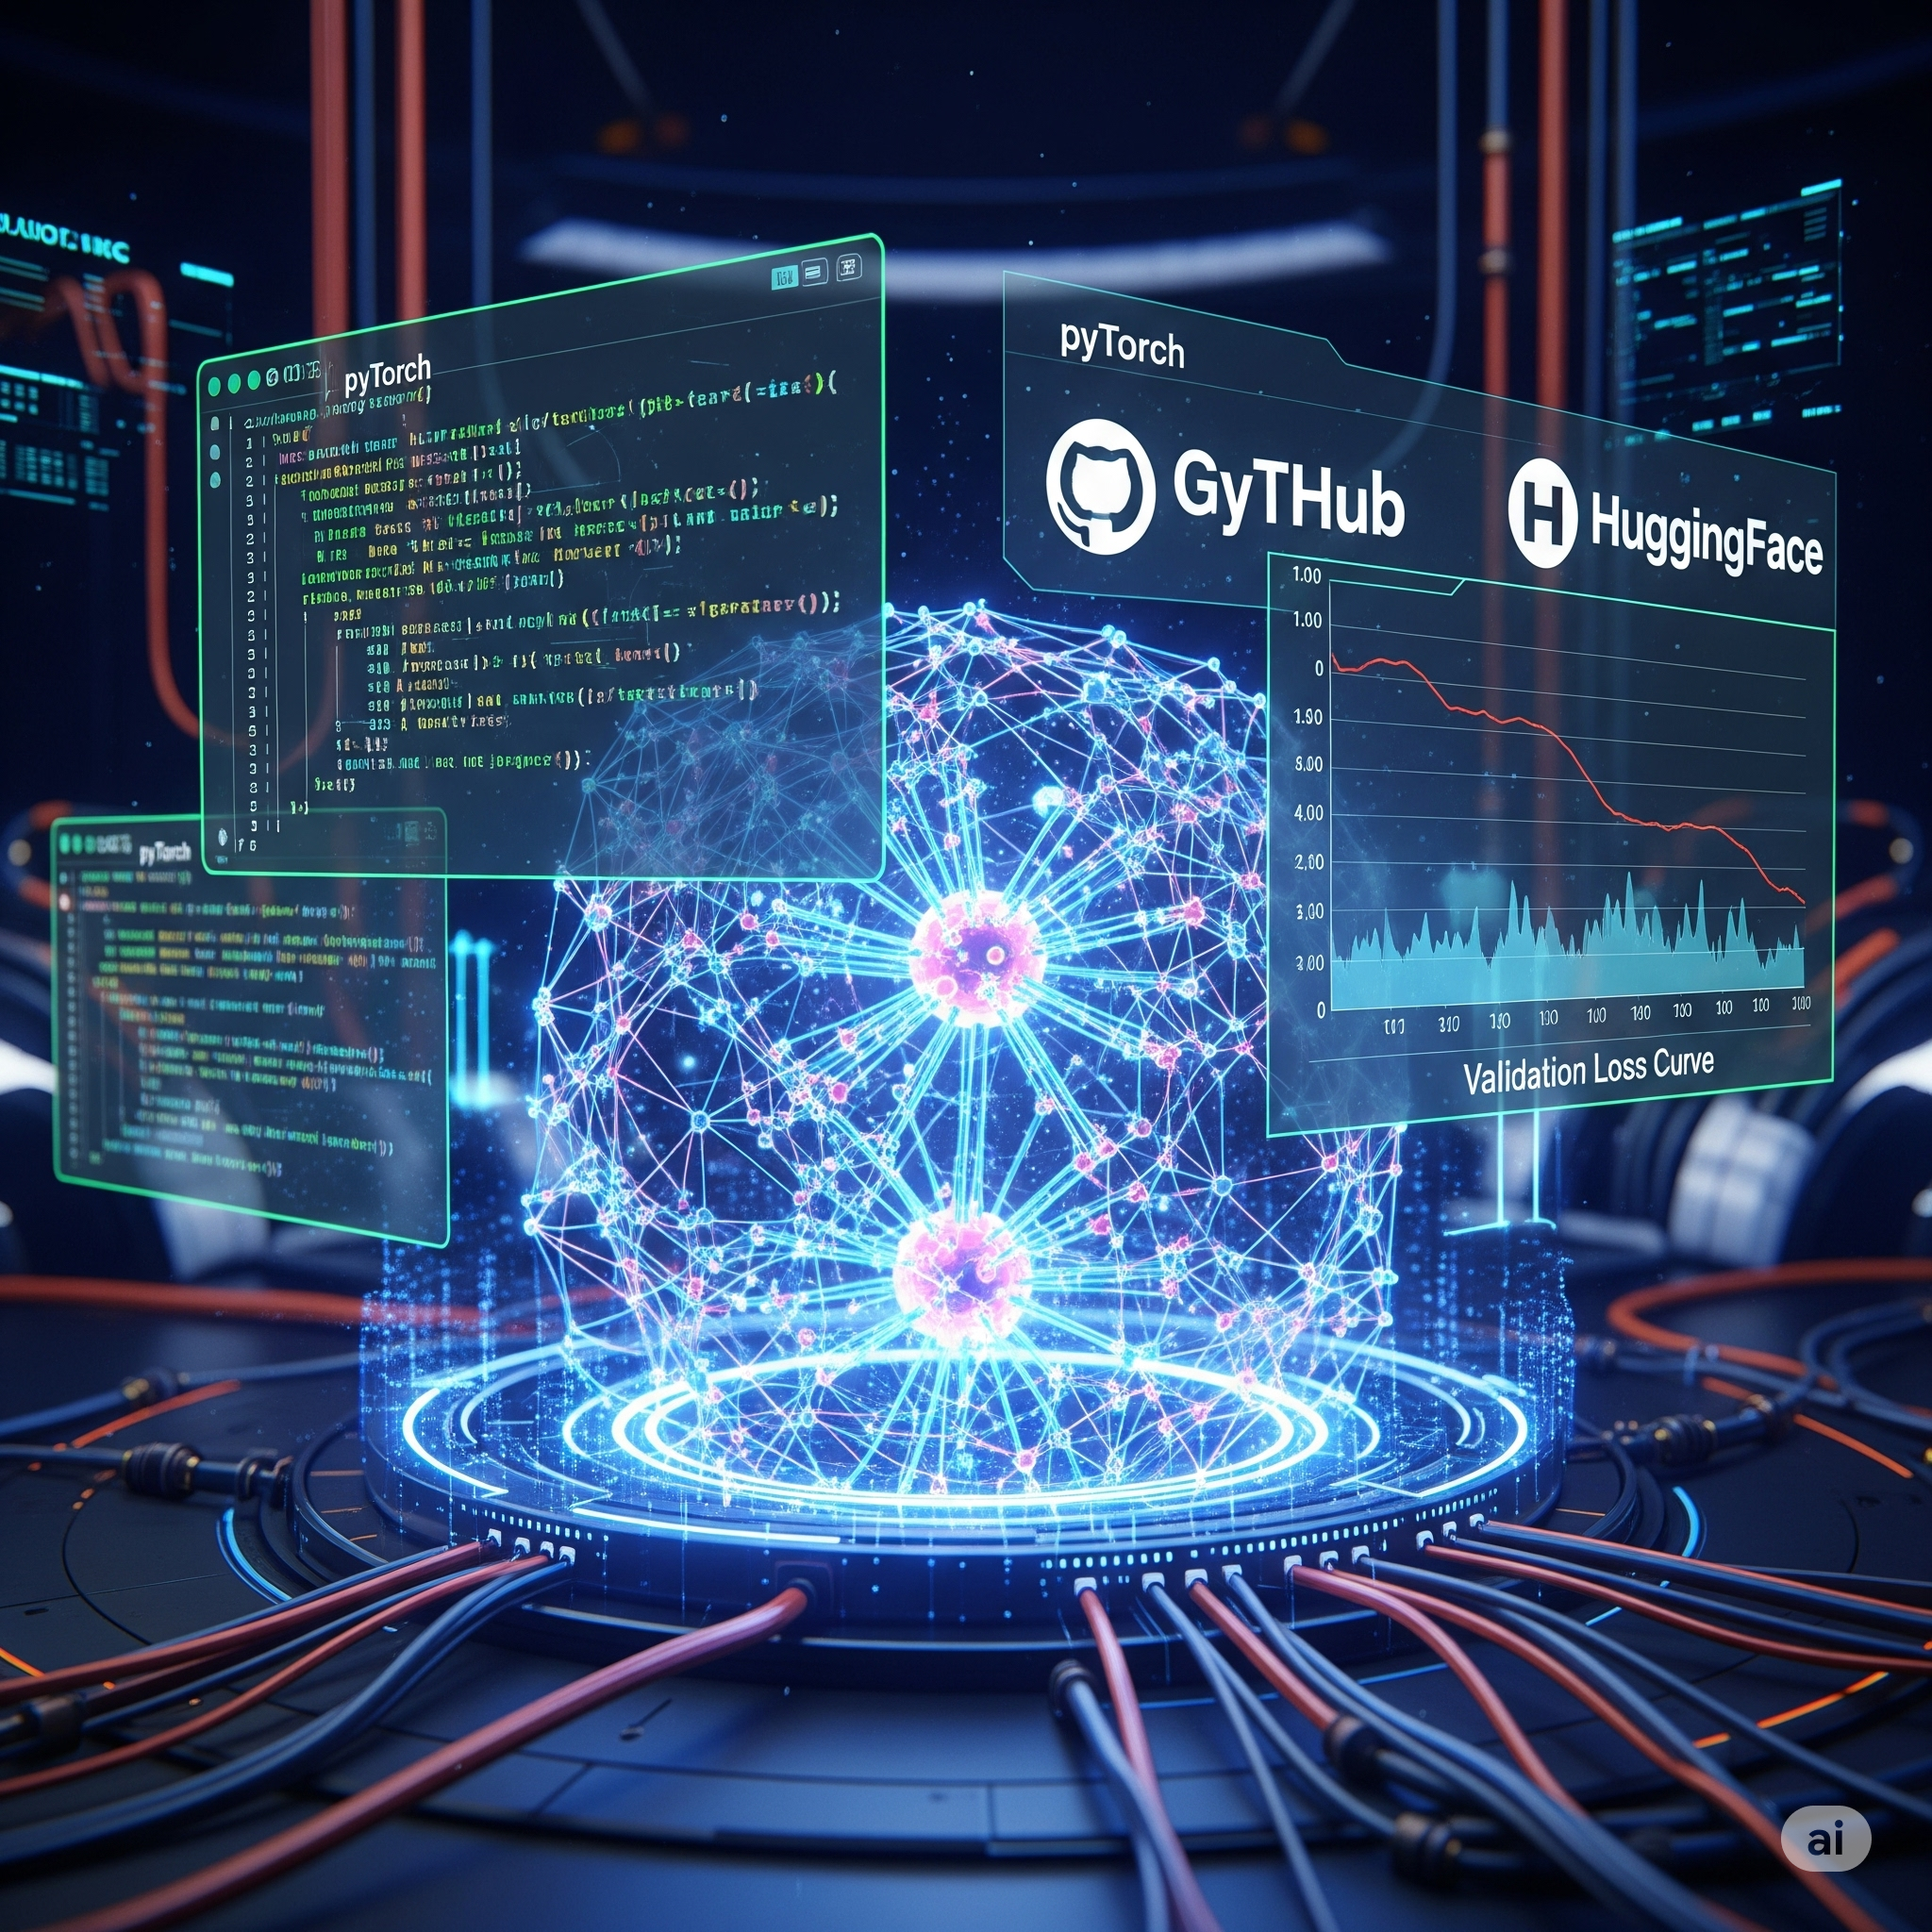
SQL SLM

Custom-Trained SQL Small Language Model (10M GPT)

Sep 2025 โ€“ Oct 2025

Architected a compact 10M-parameter GPT model from scratch in PyTorch. Implemented mixed-precision and gradient accumulation, reducing per-epoch data loading times by over 90%.

PyTorchTransformersMixed-Precision10M Params
RAG System

ContextEngine: RAG System

Built a full RAG pipeline (BM25 + FAISS) boosting grounded accuracy (42%โ†’71%). Optimized inference using vLLM.

RAGvLLMFAISS
Kafka Pipeline

Real-Time Event Stream

Designed an event-driven pipeline for e-commerce data using asynchronous producers/consumers.

KafkaDockerPython
Fine Tuning

Memory-Efficient Fine-Tuning

Implemented a QLoRa (4-bit) pipeline, reducing memory footprint by ~70% on a single T4 GPU.

QLoRaLLMPyTorch
AI Coder Buddy

AI Coder Buddy

AI agent using LangChain that plans and generates multi-file applications, decreasing development cycle time by 30%.

LangChainGroq APIAI Agents
Credit Risk

Credit Risk Model

Developed interpretable ML models that improved prediction accuracy by 20% for NBFC clients.

Scikit-learnStreamlitMLOps
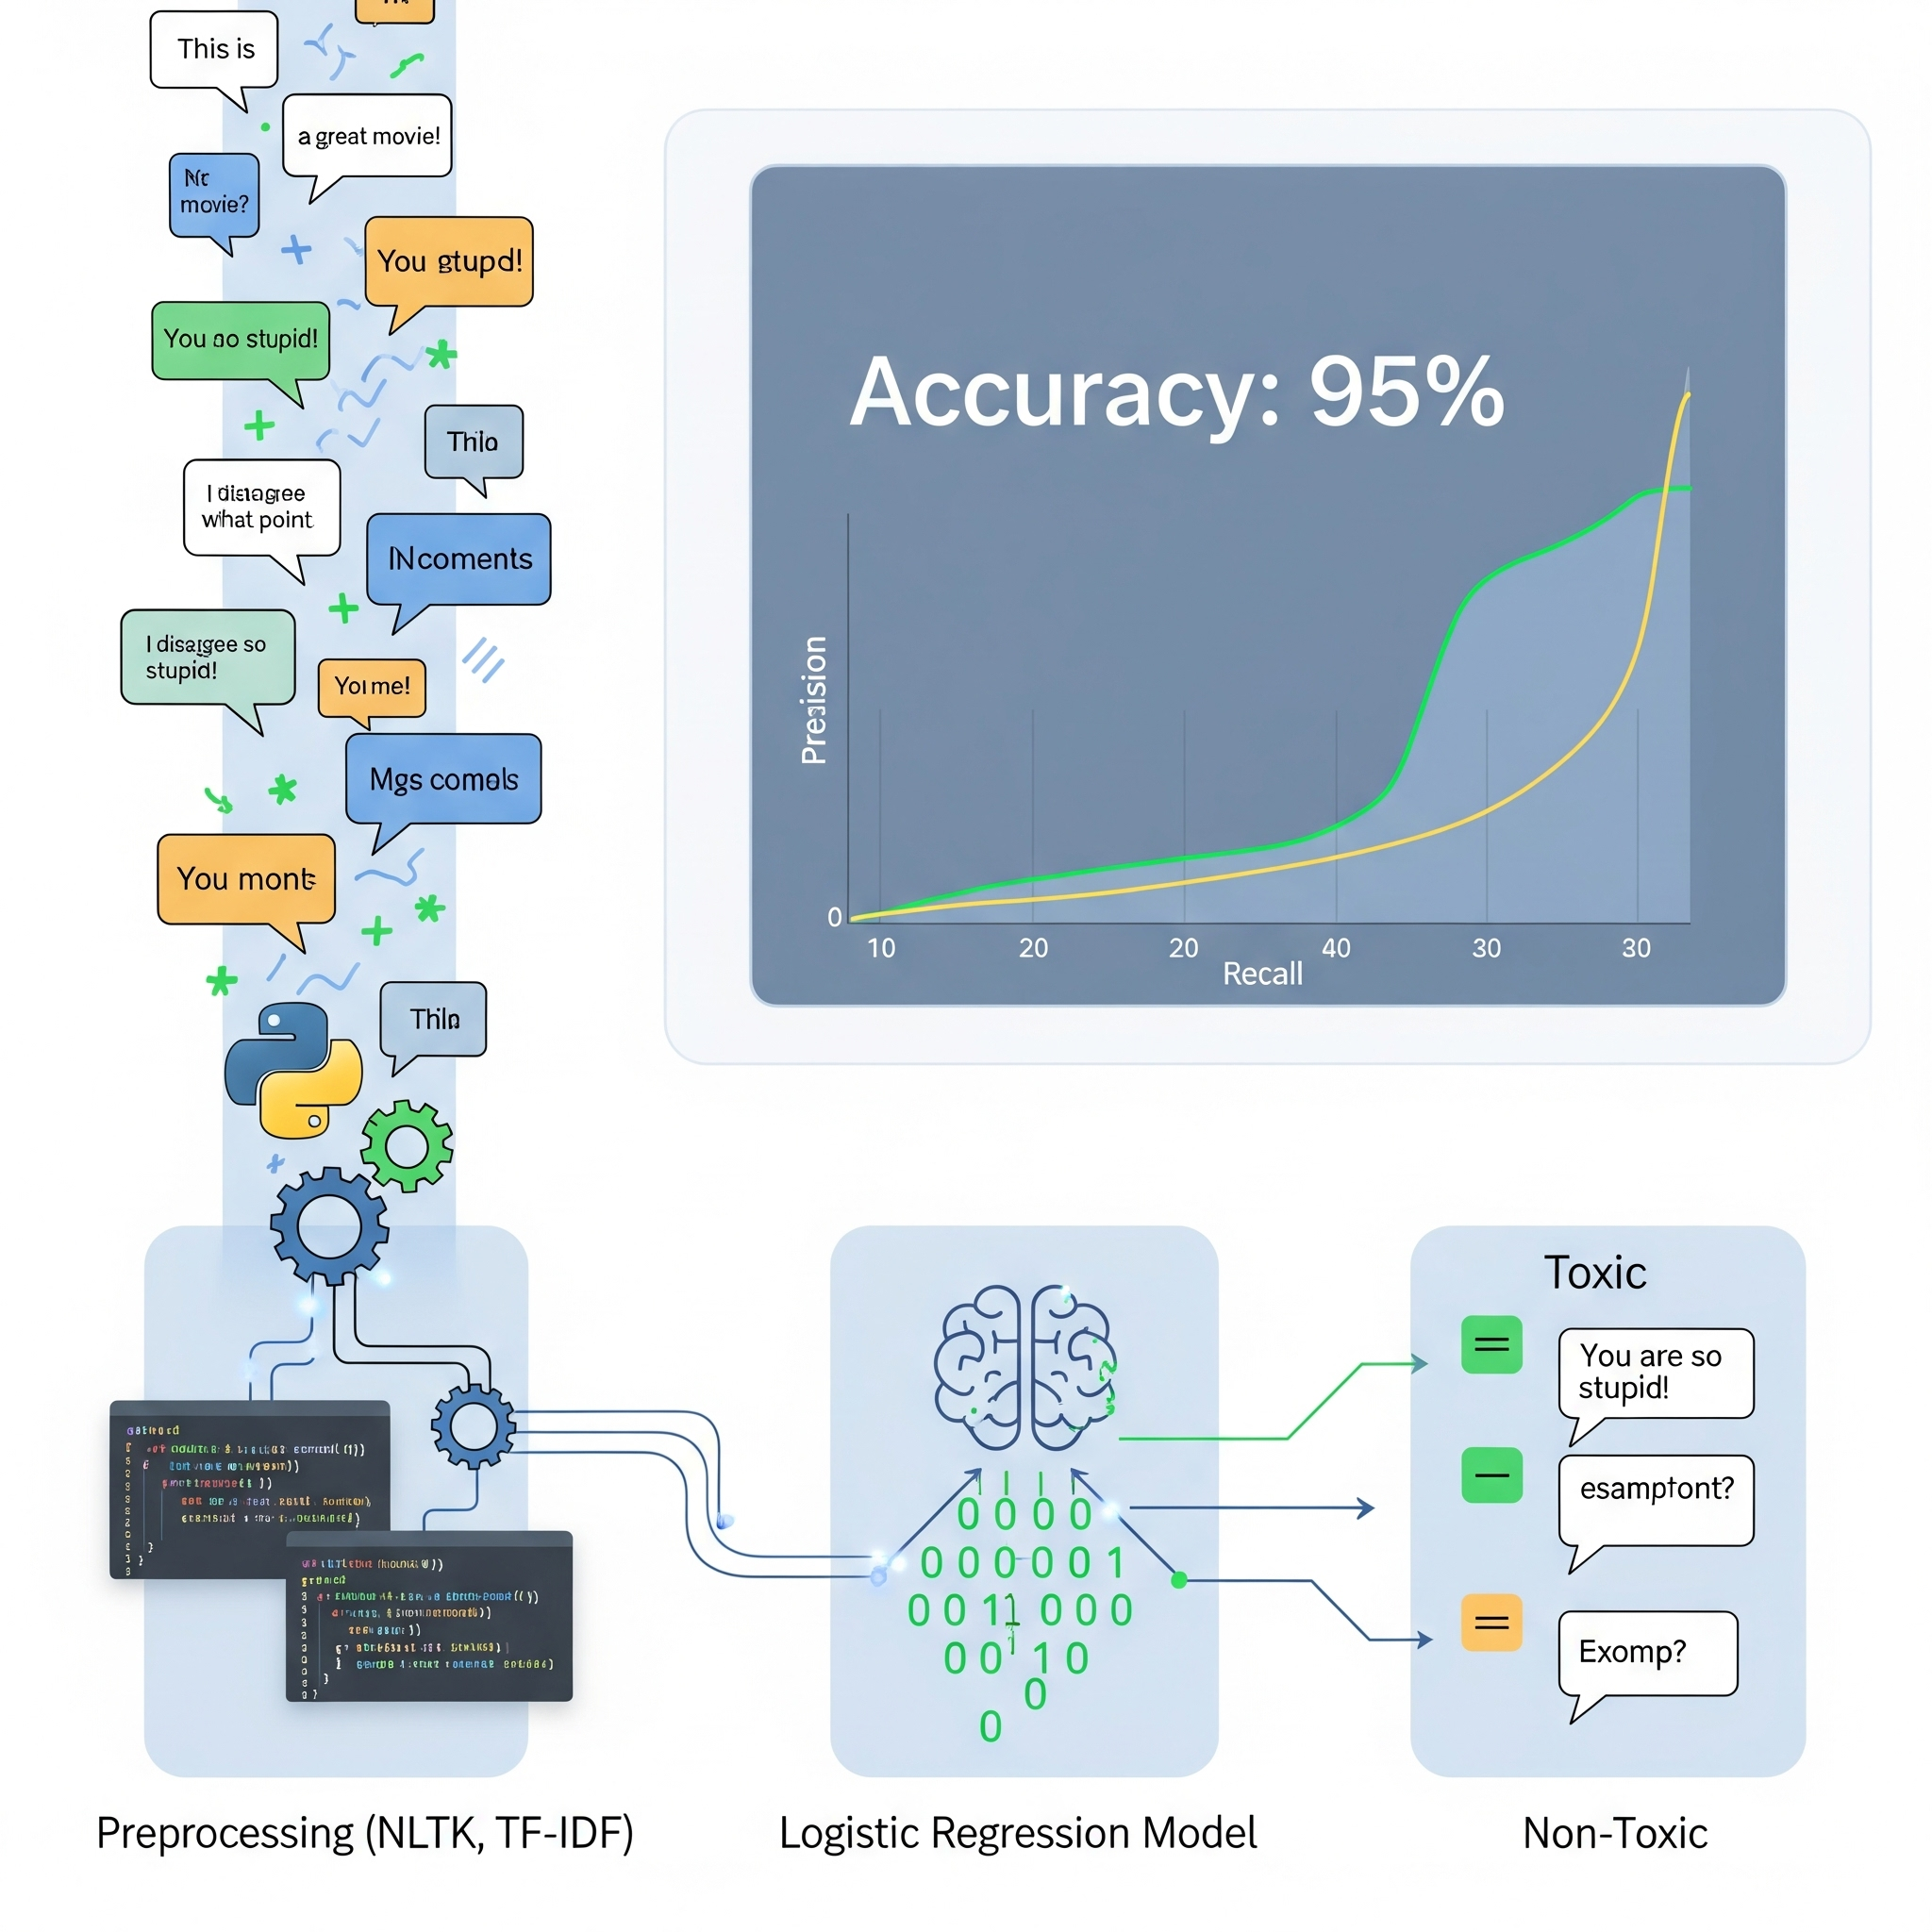
Toxic Message Detector

Toxic Message Detector

Trained a text classification model with TF-IDF on 100K+ comments, achieving 95% accuracy.

NLTKTF-IDFPandas
Multi-Modal Crew AI

Multi-Modal Crew AI

Designed a multi-agent framework that automates market research by 70% using specialized 'Researcher' and 'Writer' agents.

Gemini APILangChainStreamlit
โ„๏ธ SECTOR 05 // TECHNICAL ARSENAL
Languages

C++17/20, Python, SQL, JavaScript

Systems

Linux, Concurrency, Multithreading, TCP/IP, SIMD/AVX2, OpenMP

DevOps & Cloud

Docker, Kafka, GitHub Actions, AWS (EC2), FastAPI

Enterprise

jQuery, Dataverse, OData, Power Automate, HTML/CSS

Machine Learning

Supervised/Unsupervised Learning, Ensemble Methods, Feature Engineering, Model Evaluation

Deep Learning & GenAI

Transformers, CNNs, RNN/LSTM, Transfer Learning, Fine-Tuning, QLoRA

AI Infrastructure

PyTorch, Transformers, QLoRA, vLLM, FAISS, LLM Inference

โšก SECTOR 06 // CERTIFICATIONS, VIRTUAL EXP & GOALS

๐Ÿš€ Future Goals

Building RedOpsAI โ€“ The Future of Web Security

Over the next six months, my goal is to build RedOpsAI, a SaaS platform that makes website security testing simple and effective. The platform will provide safe and transparent scans, showing live visual feedback of potential risks without causing any harm to the site.

๐Ÿ† Certifications

Google DeepMind's AI Research Badge
Google Generative AI Leader
PMI Generative AI for PMs
Data Structures & Algorithms in C++
CodeBasics ML Masterclass
Advanced Deep Learning
McKinsey Forward (Top 1%)
System Design (LLD/HLD)

๐ŸŒ Virtual Experience

Deloitte

Virtual Software Internship, Deloitte

Forage

Debugged and refactored a 10k-line Python/SQL codebase. Added connection pooling and regression tests, reducing query failure rate by 40%.

PythonSQLDebugging
AWS

AWS APAC Solutions Architect

Forage | 10/2025 โ€“ 11/2025

Designed a scalable Elastic Beanstalk architecture for a client experiencing growth. Translated technical architecture into cost-benefit analysis.

AWSArchitectureElastic Beanstalk